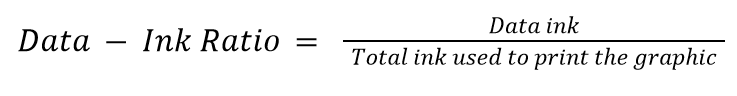Get the opportunity to grow your influence by giving your products or services prime exposure with Performance Magazine.

If you are interested in advertising with Performance Magazine, leave your address below.

    Advertise with us

    Posts Tagged ‘Data Visualization’

    What Is Data Analysis? Definition, Process, Types, and Business Examples

    FacebooktwitterlinkedinFacebooktwitterlinkedin

    Data analysis is the process of collecting, preparing, examining, and interpreting data to answer questions, identify patterns, and support decisions. In business, it helps organizations understand past performance, investigate problems, anticipate possible outcomes, and determine which actions deserve consideration.

    Data analysis involves more than producing reports or presenting figures in charts. The work begins with a clear question, continues through data preparation and examination, and ends with findings that decision-makers can understand and use.

    This guide covers:

    • What data analysis is and why it matters in business
    • The five types of data analysis: descriptive, diagnostic, predictive, prescriptive, and cognitive
    • The main stages of the data analysis process
    • Qualitative and quantitative data, including common measurement scales
    • Data quality, data cleaning, and data governance
    • Statistical methods used to examine data
    • Practical examples of data analysis in business
    • Common mistakes and the competencies needed by data analysts

    What Is Data Analysis?

    Data analysis is a systematic process of examining data to extract information, identify patterns, test assumptions, and answer questions. It involves activities such as organizing raw data, correcting errors, exploring distributions, applying statistical techniques, and communicating findings.

    The purpose of analysis depends on the question being asked. A sales manager might want to understand why revenue fell last quarter. A human resources team might investigate employee turnover. An operations manager might examine delays in service delivery. Each situation requires relevant data, appropriate analytical methods, and an interpretation connected to the decision at hand.

    Data analysis is also closely related to data-driven decision-making. Rather than relying exclusively on instinct or personal experience, decision-makers use evidence from data alongside professional judgment, operational knowledge, and an understanding of the business context.

    Why Does Data Analysis Matter in Business?

    Organizations collect data through transactions, customer interactions, operational systems, surveys, financial records, and other activities. However, having data does not automatically lead to better decisions. The information must be reliable, relevant, and interpreted correctly.

    Data analysis can help organizations:

    • Monitor performance. Compare actual results with targets, historical results, or established standards.
    • Identify patterns. Examine changes across time periods, business units, customer groups, or operational processes.
    • Investigate problems. Explore possible explanations for unexpected results and determine what additional evidence is needed.
    • Anticipate outcomes. Use historical patterns and statistical models to estimate future demand, risks, or performance.
    • Compare alternatives. Examine potential outcomes under different assumptions or courses of action.
    • Communicate findings. Present complex information through charts, tables, dashboards, and concise explanations.

    Research provides evidence of an association between data-driven decision-making and organizational performance. In a study of 179 large publicly traded firms, Erik Brynjolfsson, Lorin Hitt, and Heekyung Kim reported that firms adopting data-driven decision-making had output and productivity 5% to 6% higher than expected given their other investments and information technology use. Read the study, Strength in Numbers: How Does Data-Driven Decision-Making Affect Firm Performance?.

    This finding should be interpreted within the study’s scope. It does not mean that every organization will achieve the same productivity improvement simply by collecting more data. The quality of the data, analytical approach, organizational practices, and use of the findings all matter.

    What Are the Five Types of Data Analysis?

    The Certified Data Analysis Professional course materials of The KPI Institute distinguish five types of data analysis: descriptive, diagnostic, predictive, prescriptive, and cognitive. Each type addresses a different question and supports a different stage of decision-making.

    1. Descriptive Analysis: What Happened?

    Descriptive analysis examines historical or current data to summarize what has happened. It gives decision-makers an overview of performance, activity, or conditions during a defined period.

    Common techniques include frequency tables, summary statistics, charts, pivot tables, and dashboards.

    Business example: A retailer reviews monthly sales by product category and finds that revenue declined in three categories during the previous quarter. Descriptive analysis identifies the decline and shows where it occurred, but it does not explain the reasons behind it.

    2. Diagnostic Analysis: What Happened and Why?

    Diagnostic analysis investigates the factors that may explain an observed result. It goes beyond summarizing performance and examines relationships, differences, and possible contributing factors.

    Analysts may compare groups, examine changes over time, investigate unusual results, or test hypotheses. A pattern or correlation can suggest a possible explanation, but it does not automatically establish causation.

    Business example: After identifying a decline in sales, the retailer compares sales by location, product availability, promotional activity, and customer segment. The analysis may reveal that the decline was concentrated in locations affected by frequent stock shortages. Further investigation would be needed to determine how much those shortages contributed to the result.

    3. Predictive Analysis: What Might Happen?

    Predictive analysis uses historical data, statistical models, and relevant variables to estimate future outcomes. It supports forecasting and planning under uncertainty.

    Common applications include demand forecasting, customer churn prediction, sales projections, and risk estimation. Predictions are estimates, not guarantees, and their reliability depends on the data, assumptions, model quality, and changes in the conditions being studied.

    Business example: A retailer uses previous sales, seasonal patterns, and stock records to estimate demand for the next quarter. The forecast helps the purchasing team prepare inventory, although unexpected events may still affect actual demand.

    4. Prescriptive Analysis: What Should We Do?

    Prescriptive analysis examines possible actions and their potential outcomes to support decisions. It can use simulation, optimization, and scenario analysis to compare alternatives under different assumptions or constraints.

    Rather than stopping at a forecast, this type of analysis considers how different decisions might affect the expected result.

    Business example: Based on its demand forecast, a retailer compares several inventory plans. One option prioritizes lower storage costs, while another prioritizes product availability. Prescriptive analysis helps the team examine the trade-offs before selecting an approach.

    5. Cognitive Analysis: How Can Analysis Become More Automated?

    Cognitive analysis, as presented in The KPI Institute’s course materials, involves self-learning and automated simulation and actions. It represents a more advanced analytical approach in which systems can learn from data and perform certain analytical or operational tasks with less direct human intervention.

    Business example: A business uses a system that learns from transaction patterns and flags unusual activity for review. Depending on the system’s design and authorization, automated processes may also initiate predefined actions. Human oversight remains important, particularly when decisions carry significant consequences.

    These five types can complement one another. An organization might first describe a performance problem, investigate its possible causes, estimate what could happen next, compare possible responses, and automate selected tasks where appropriate.

    What Is the Data Analysis Process?

    The data analysis process is a sequence of activities that turns raw data into findings that can support a decision. The exact workflow varies by project, but the following stages provide a practical structure.

    1. Define the Business Question

    Start by identifying the problem, decision, or objective the analysis must address. A broad request such as “analyze our sales” is difficult to act on without more context.

    A focused question could be: “Which product categories contributed most to the decline in quarterly sales?” The question helps determine which data is needed, what comparisons are relevant, and what the final analysis should explain.

    2. Collect the Relevant Data

    Data may come from primary or secondary sources.

    • Primary data is collected directly for a particular purpose. Examples include survey responses, interviews, observations, and newly collected or real-time measurements.
    • Secondary data consists of information that has already been collected or recorded. Examples include historical sales records, previous survey results, published datasets, and existing organizational reports.

    The analyst should check whether the available data is relevant to the question, sufficiently complete, and appropriate for the intended analysis.

    3. Clean and Prepare the Data

    Raw data may contain missing entries, duplicate records, inconsistent labels, errors, or different formats. Data preparation addresses these issues before the analysis proceeds.

    Common activities include:

    • Identifying and handling duplicate records
    • Checking missing or invalid values
    • Standardizing dates, units, labels, and categories
    • Correcting errors where the original information can be verified
    • Checking that fields follow expected formats and rules

    Data cleaning requires care. A missing value should not automatically be replaced with zero, for example, because zero may represent a real observation. The appropriate treatment depends on what the missing information means and how it affects the analysis.

    4. Explore the Data

    Exploratory analysis helps analysts understand the structure and characteristics of a dataset before drawing conclusions.

    This stage may involve frequency tables, pivot tables, summary statistics, and charts. Analysts can examine distributions, identify unusual observations, compare categories, and look for patterns that warrant further investigation.

    Exploration may also reveal that the original question needs refinement or that additional data is required.

    5. Apply Analytical Methods

    Select methods that match the question and the type of data available. A summary of monthly revenue may require descriptive statistics and a line chart. Comparing several groups may require a statistical test. Estimating future demand may call for regression or time-series analysis.

    The choice of method should reflect the objective, measurement scale, sample, assumptions, and limitations of the data.

    6. Interpret and Communicate the Findings

    Analysis is incomplete until its findings are explained in a form that the intended audience can use. A report or dashboard should identify the main result, explain relevant comparisons, and distinguish evidence from assumptions or possible explanations.

    Good communication also acknowledges limitations. Analysts should explain when data is incomplete, when a sample may not represent the full population, or when an observed relationship does not establish causation.

    7. Support a Decision and Review the Outcome

    Decision-makers use the findings alongside business priorities, constraints, and professional judgment. After an action is taken, its results can be monitored and compared with expectations.

    This feedback can inform the next analysis cycle. For example, a demand forecast can be compared with actual sales to assess its accuracy and identify opportunities to improve future forecasts.

    What Are the Main Types of Data?

    The type of data collected affects how it should be organized, summarized, and analyzed. Two broad categories are qualitative and quantitative data.

    Qualitative Data

    Qualitative data describes categories or characteristics rather than numerical quantities. It is often represented by labels or groups.

    Examples include department names, customer feedback categories, product types, and satisfaction levels recorded as ordered categories.

    Two common forms are:

    • Nominal data: Categories without an inherent order, such as department, product type, or payment method.
    • Ordinal data: Categories with a meaningful order, such as low, medium, and high satisfaction.

    Although ordinal categories have an order, the distance between them is not necessarily equal. An analyst should not assume that the difference between “low” and “medium” is identical to the difference between “medium” and “high.”

    Quantitative Data

    Quantitative data represents numerical quantities that can be counted or measured.

    Examples include sales revenue, number of customer complaints, processing time, and number of completed transactions.

    Two common forms are:

    • Discrete data: Countable values, such as the number of service requests received in a day.
    • Continuous data: Measurements that can take a range of values, such as delivery time, temperature, or weight.

    Quantitative data may also use different measurement scales:

    • Interval scale: Equal differences between measurements are meaningful, but zero does not represent the complete absence of the measured quantity. Temperature in Celsius is a common example.
    • Ratio scale: Equal differences are meaningful and zero represents the absence of the measured quantity. Examples include duration, distance, and the number of completed transactions.

    Understanding these distinctions helps analysts select suitable calculations, charts, and statistical methods.

    What Is Data Quality and Data Governance?

    Data quality refers to how suitable data is for its intended use. Poor-quality data can produce misleading summaries, unreliable comparisons, and flawed conclusions, even when an analyst uses an appropriate statistical method.

    The KPI Institute’s course materials identify six dimensions of data quality:

    Dimension What it means
    Uniqueness Records are not unintentionally duplicated.
    Accuracy Data correctly represents the information it is intended to record.
    Timeliness Data is available and current enough for its intended use.
    Completeness Required information is present.
    Conformity Data follows the required formats, standards, or rules.
    Consistency Data does not conflict across records, systems, or reporting periods without an explainable reason.

    These dimensions are related but distinct. A dataset may be complete yet inaccurate, or accurate when collected but too old for a time-sensitive decision.

    Data governance establishes roles and responsibilities for managing data and maintaining its quality. The course materials describe four roles:

    • Data architect: Designs, creates, deploys, and manages data sets and the relationships between them.
    • Data steward: Oversees the quality and fitness of specific data sets, including their content and metadata.
    • Data quality analyst: Checks whether data is suitable for its intended use in decision-making and planning.
    • IT operations: Oversees the operation of computer systems and related infrastructure.

    These responsibilities help organizations manage data consistently. The specific division of work may differ across organizations, depending on their size, systems, and governance arrangements.

    What Data Analysis Methods Do Businesses Use?

    Data analysts use a range of statistical and analytical methods. The appropriate method depends on the question, the data, and the assumptions that can reasonably be made.

    Descriptive Statistics

    Descriptive statistics summarize the main characteristics of a dataset. They can be used to examine one variable or relationships between two variables.

    Common measures include:

    • Measures of central tendency: Mean, median, and mode, which describe different aspects of a typical or common value.
    • Measures of spread: Range, variance, and standard deviation, which describe how values differ or disperse.
    • Frequency distributions: Counts or proportions showing how often values or categories occur.
    • Cross-tabulations: Tables that compare two categorical variables.

    For example, a service team might calculate average resolution time and compare it across support categories. The average provides a useful summary, while the distribution and spread can reveal whether a small number of unusually long cases are affecting the result.

    Inferential Statistics

    Inferential statistics use data from a sample to estimate or test claims about a larger population. The strength of the conclusions depends on the sampling approach, sample size, measurement quality, and assumptions behind the method.

    Two broad applications are estimation and hypothesis testing. Estimation uses sample data to estimate a population characteristic, sometimes with an interval that expresses uncertainty. Hypothesis testing evaluates evidence relevant to a specified claim.

    Hypothesis Testing

    Hypothesis testing follows a structured process. An analyst states a hypothesis, selects an appropriate test, identifies the decision criteria, performs the analysis, and interprets the results in context.

    Methods covered in the course materials include the Z-test, t-test, analysis of variance (ANOVA), and chi-square test. Each serves different purposes and relies on particular assumptions. They are not interchangeable, so the analyst must match the test to the question and the data.

    A statistically significant result does not necessarily mean that an effect is large or important for the business. The size of the effect, uncertainty, practical implications, and quality of the study also matter.

    Regression and Time-Series Analysis

    Regression analysis examines relationships between a response variable and one or more explanatory variables. It can help estimate associations and, when the assumptions and design support it, contribute to prediction.

    Time-series analysis examines data recorded over time. It can help identify patterns, trends, and recurring fluctuations, and may be used to forecast future observations.

    Neither method automatically proves that one factor caused another. Analysts must consider other explanations, data limitations, and the assumptions behind their models.

    What Are Examples of Data Analysis in Business?

    The following examples illustrate how data analysis concepts can be applied to common business questions. They are hypothetical applications, not claims about the results of a specific organization.

    Business area Question Possible analysis How findings may be used
    Sales Which products contributed to a decline in revenue? Compare sales by product, location, and period. Investigate underperforming categories and review sales plans.
    Customer service Why are some requests taking longer to resolve? Compare resolution times by request type, team, and workload. Identify areas that may require process review or additional support.
    Human resources How does employee turnover vary across departments? Examine turnover rates by department and period. Identify patterns that merit further investigation.
    Finance How closely does actual spending match the budget? Compare planned and actual expenditure by category. Review significant differences and update forecasts where appropriate.
    Operations How accurately can demand be forecast? Analyze historical demand and test forecasting methods. Support inventory, staffing, and capacity planning.
    Marketing Which campaign is associated with more conversions? Compare conversion rates across campaigns and audience groups. Review campaign performance while accounting for differences between groups.

    The key is to start with a clear business question and select a method that can answer it. A chart may reveal a pattern, but additional analysis may be required to explain that pattern or determine what action is appropriate.

    What Are Common Data Analysis Mistakes?

    A technically correct calculation can still lead to a poor decision if the data, method, or interpretation is unsuitable. Common mistakes include:

    • Starting without a clear question. Collecting and exploring data without a defined objective can lead to unnecessary work and findings that do not address a business need.
    • Ignoring data quality. Duplicates, missing values, inconsistent formats, and inaccurate records can distort results.
    • Choosing an unsuitable method. A statistical technique should match the research question, data type, and assumptions.
    • Confusing correlation with causation. Two variables may change together without one causing the other.
    • Overlooking the sample. A sample may not represent the population the analyst wants to understand.
    • Treating forecasts as certainties. Predictions depend on data, assumptions, and conditions that may change.
    • Reporting numbers without context. A result becomes more useful when readers know the comparison, time period, baseline, and limitations.
    • Communicating too much technical detail. Decision-makers need enough explanation to assess the findings without losing sight of the business question.

    A disciplined analysis documents the methods used, checks the quality of the evidence, and communicates both the findings and their limitations.

    How Can Professionals Develop Data Analysis Competencies?

    Data analysis requires a combination of technical knowledge, analytical judgment, and communication skills. Professionals need to understand the data they are examining, select appropriate methods, and explain what the findings mean for a decision.

    The Certified Data Analysis Professional course materials cover data types, data cleaning, exploratory analysis, descriptive and inferential statistics, sampling, hypothesis testing, regression, time-series topics, and data governance. They also discuss the use of tools such as Excel for data exploration and chart creation.

    Professionals can develop their competencies by:

    1. Strengthening statistical foundations. Learn how to summarize data, interpret distributions, understand sampling, and select appropriate tests.
    2. Practicing data preparation. Work with missing values, duplicates, inconsistent formats, and quality checks.
    3. Learning visualization techniques. Choose charts and tables that communicate the relevant comparison without distorting the data.
    4. Connecting analysis to business questions. Practice translating a general concern into a specific, answerable question.
    5. Explaining findings clearly. Present the main result, supporting evidence, limitations, and possible implications.
    6. Applying methods to realistic cases. Use business scenarios to practice the complete process, from defining the question to communicating the findings.

    Research on data-driven decision-making also offers a useful reminder that analysis should connect to organizational practice. A 2023 study by Raazia Gul and colleagues examined banks in Pakistan over the 2016–2020 period and reported a 4% to 7% productivity increase among banks adopting data-driven decision-making practices, depending on adjustment to change. The findings are specific to the study’s banking-sector context. Read The Empirical Nexus between Data-Driven Decision-Making and Productivity: Evidence from Pakistan’s Banking Sector.

    Developing data analysis competencies is therefore not just about learning software or memorizing statistical formulas. It also involves asking precise questions, checking evidence, recognizing uncertainty, and presenting conclusions that decision-makers can assess.

    Frequently Asked Questions About Data Analysis

    What is the main purpose of data analysis?

    The main purpose of data analysis is to examine data and produce findings that help answer questions, identify patterns, investigate problems, estimate outcomes, and support decisions.

    What are the five types of data analysis?

    The five types covered in The KPI Institute’s Certified Data Analysis Professional course materials are descriptive, diagnostic, predictive, prescriptive, and cognitive analysis. They address what happened, why it happened, what might happen, what actions could be taken, and how learning and automated actions may be incorporated into analytical systems.

    What is the difference between data analysis and data analytics?

    The terms are often used interchangeably, although some organizations distinguish them. Data analysis commonly refers to examining data to answer a question, while data analytics may refer to the broader set of methods, tools, and practices used to generate insights and support decisions. The intended meaning depends on the context.

    What are the main steps in the data analysis process?

    A typical process includes defining the question, collecting relevant data, cleaning and preparing it, exploring the data, applying analytical methods, interpreting and communicating the findings, and reviewing the outcome after a decision is made.

    What is the difference between qualitative and quantitative data?

    Qualitative data describes categories or characteristics, such as product type or customer feedback category. Quantitative data represents numerical quantities, such as revenue, duration, or the number of transactions. The distinction affects which calculations and analytical methods are suitable.

    Why is data quality important in data analysis?

    Data quality affects whether the findings accurately represent the situation being studied. Missing, inaccurate, duplicated, outdated, or inconsistent data can distort results and lead to inappropriate conclusions.

    What tools are used for data analysis?

    Tools depend on the task. Spreadsheets such as Excel can support data cleaning, exploration, calculations, and charts. More complex work may involve statistical software, programming languages, databases, or business intelligence platforms. The tool should suit the question, data, and required method.

    Does data analysis guarantee better business decisions?

    No. Data analysis can improve the evidence available to decision-makers, but it does not guarantee a good outcome. Results depend on data quality, the analytical method, interpretation, organizational context, and how findings are used. Decisions may also require professional judgment and consideration of factors that are not captured in the data.

    Editor’s Note

    This guide draws on The KPI Institute’s Certified Data Analysis Professional course. The external research references provide empirical context on data-driven decision-making and organizational performance.

    KPI data visualization: key benefits, popular formats, and design principles

    FacebooktwitterlinkedinFacebooktwitterlinkedin


    Today’s organizations drown in information waves. When leveraging data for actionable insights needed to drive strategic decision-making and sound performance measurement, visualization makes that data comprehensible and accessible. Specifically, key performance indicator (KPI) data visualization aims to communicate key performance metrics and trends in a way that is clear, concise, and impactful. 

    KPI data visualization benefits for organizations

    KPI data visualization offers a multitude of benefits for organizations seeking to make data-driven decisions: 

    Enhanced data understanding: Visualizing KPIs makes it easier and faster to grasp complex data sets, identify patterns, and uncover hidden trends that would otherwise remain obscured in numerical form. KPI visualization provides insights regarding the entity’s current situation and helps a better understanding of the market.

    Improved decision-making: Providing a clear and concise overview of key performance metrics, empowers decision-makers as KPI data visualization prioritizes evidence rather than intuition. 

    Effective communication and collaboration: Visual representations of KPIs facilitate effective communication and collaboration across teams by enabling stakeholders to share insights, align strategies, and achieve desirable goals. Additionally, KPI data visualization fosters accountability by transparently tracking performance against established goals, motivating individuals and teams to take ownership of their results, and promoting a data-driven culture within organizations to encourage data-informed decision-making at all levels.

    Popular formats for KPI data visualization

    The art of data visualization lies in presenting complex information in an informative and engaging way for all stakeholders. The most popular and effective techniques are as follows:

    Charts and graphs: Bar charts and line graphs are effective ways to show trends and comparisons. Bar charts are effective in category comparison within a single measure. The line graph is mostly used to visualize changes in one value relative to another. 

    Maps and heatmaps: These visual tools are perfect for showcasing geographical data and identifying areas of concentration or dispersion.

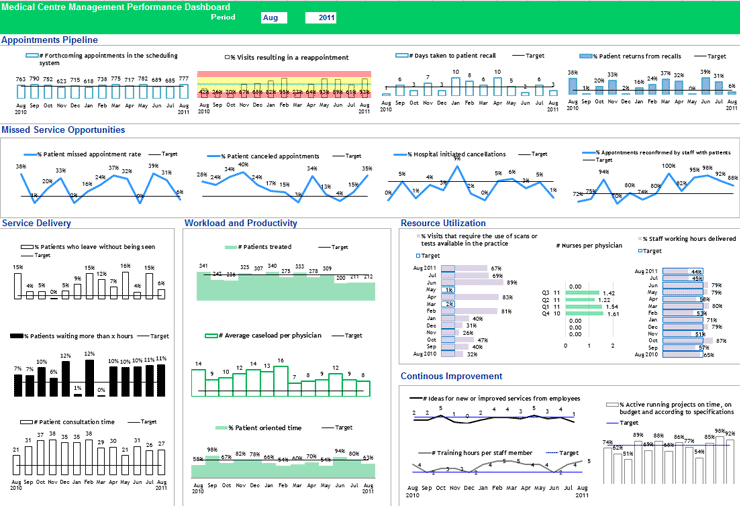
    Dashboards: Combining multiple visualizations on a single screen provides a comprehensive overview of KPIs (see Figure 1).

    Medical Practice Dashboard

    Figure 1. An example of medical center management performance dashboard | Source: The KPI Institute (2023), Medical Practice Dashboard

    Major principles for effective KPI data visualization

    To harness the power of KPI data visualization effectively, organizations should adhere to a set of key principles as best practices: 

    Clarity and simplicity: Prioritize clarity and simplicity in data visualizations by avoiding cluttered charts and excessive complexity that may obscure insights.

    Contextualization: Provide context for visualized KPIs by including relevant information, such as benchmarks, targets, and historical trends.

    Visual Hierarchy: Establish a clear visual hierarchy to guide the viewer’s attention towards the most important KPIs and trends.

    Storytelling: Utilize data visualizations to tell a compelling story, highlighting key insights and communicating performance trends effectively.

    KPI data visualization has emerged as a transformative tool to support organizations in extracting meaningful insights from their vast data repositories. The first move for effective KPI data visualization is to embrace data culture across all organizational levels. The second step is to determine data constraints, such as the type of data, the number of variables, and the type of pattern one is trying to show (comparison, part-to-whole, hierarchy, etc.). 

    If you want to achieve effective KPI visual representations to support the decision-making process,? sign up for The KPI Institute’s Certified Data Visualization Professional course.

    How data-ink ratio imposed Minimalism on data visualization

    FacebooktwitterlinkedinFacebooktwitterlinkedin

    Image source: Алекс Арцибашев | Unsplash

    In 1983, American professor of statistics and computer science Edward Tufte introduced the concept of data-ink ratio in his famous book, “The Visual Display of Quantitative Information.” Data-ink ratio is a pioneering disciplinary theory in data visualization that has been highly influential in recommended practices and teachings, with its excellency reflecting a minimalistic style of design. The art movement of Minimalism is noticeable in Tufte’s theory, even though he did not deliberately mention it. However, academic research shows that data-ink ratio generated mixed responses, resulting in the need for more complex frameworks in data visualization.

    What is data-ink ratio?

    Tufte’s Data-Ink Ratio is built on his preposition that “data graphics should draw the viewer’s attention to the sense and substance of the data, not to something else”. The conceptual formula is:

    data-ink ratio equation


    “Data ink” means what is absolutely necessary to show the data. The word “ink” is used because the theory was formulated in the age of print graphics dominance. The equivalent of “ink” in the digital world today is “pixels.” Data-ink ratio aims to find and maximize the share of informative elements out of the total elements used in a chart, raising a ratio of 1 as the highest goal. A visualization with such a ratio is the one that only contains elements that show the data, with no decorations or redundancies.

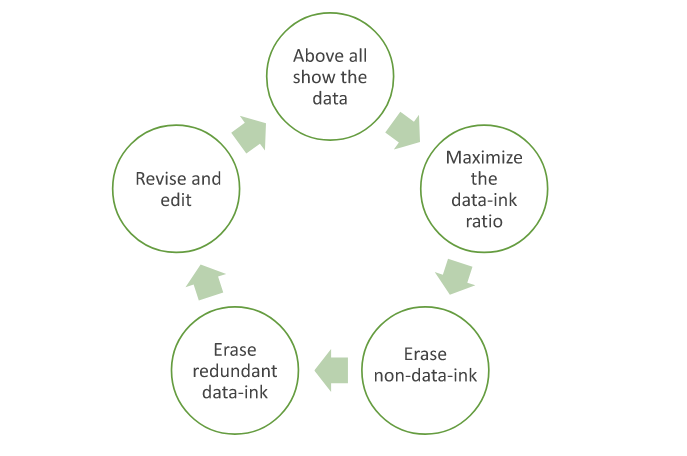
    Tufte asserted this goal by articulating two erasing principles: “erase non-data-ink, within reason” and “erase redundant data-ink, within reason.” For these two types of ink, he coined the term “chartjunk.” The excessive elements to get rid of include decorations, background images, unnecessary colors, gridlines, axes, and tick marks. He said that the principles should be applied through editing and redesign. This led to the structuring of the process of data visualization as a cyclical one that ends when the most minimal output is reached.

    The cycle goes as follows, in Tufte’s words:

    Tufte's process of editing visuals

    Illustration by Islam Salahuddin

    Minimalism in data visualization

    Minimalism became one of the most important and influential movements during the professor’s young age in the 1960s. Minimalism is defined by Cambridge dictionary as “a style in art, design, and theater that uses the smallest range of materials and colors possible, and only very simple shapes or forms.” It is a kind of reductive abstract art that is characterized by “plain geometric configurations” that lack “any decorative… flourishes.”

    That can be juxtaposed with what Tufte instructed under the data-ink ratio theory: to achieve a data visualization that is simple and, therefore, minimal. Tufte’s theory suggests that such simplicity can deliver a message that is clear, precise, and efficient. As a result, it could reduce the time required for the user to perceive the visualization.

    Applying tufte's principles

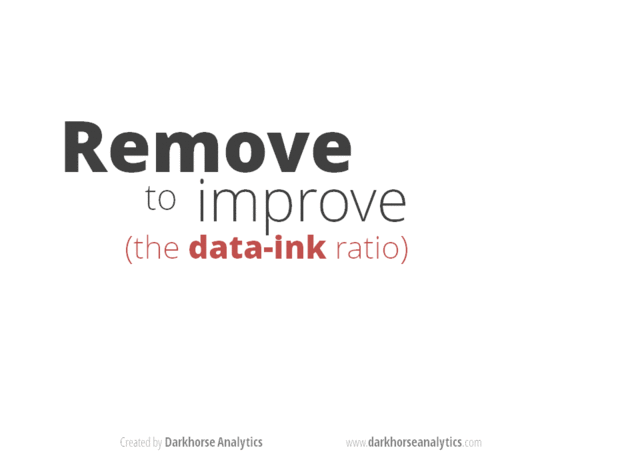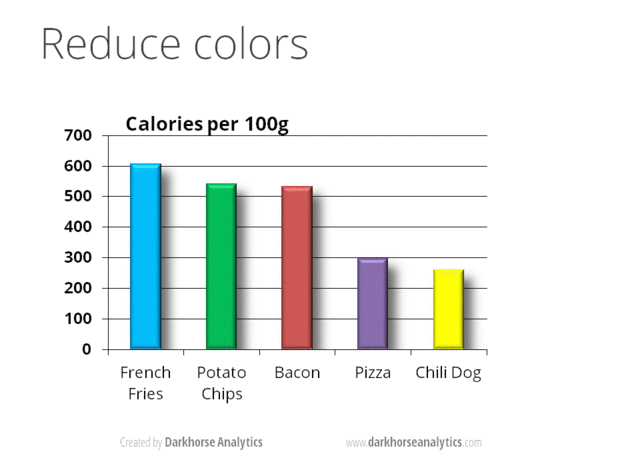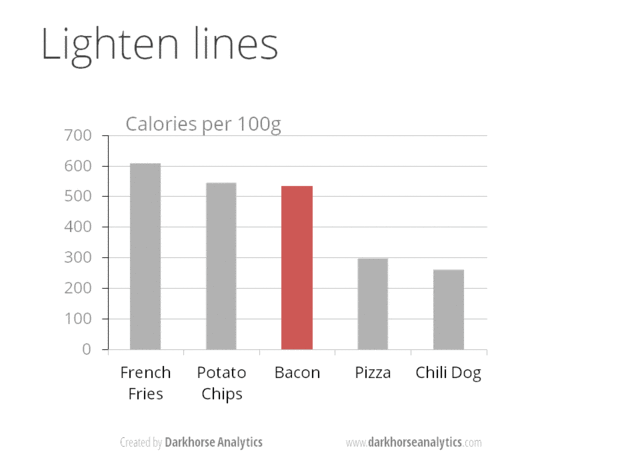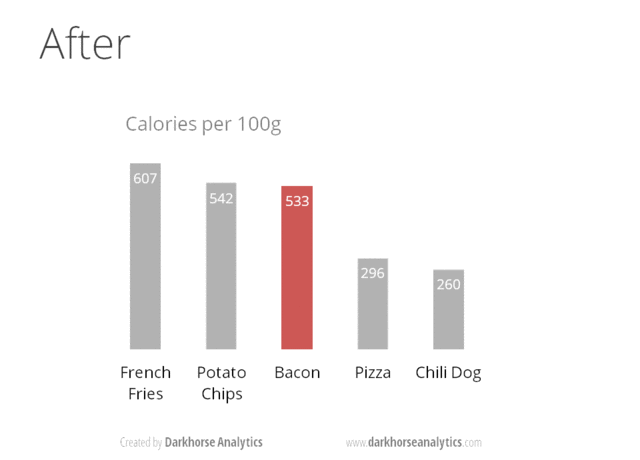
    One of the many posts surfacing the internet to exemplify applying Tufte’s reductive principles on a bar chart. | Image Source: Darkhorse Analytics

    Tufte’s priorities match the needs of the fast-paced business world. In business, saving time means saving cost and therefore maximizing profit. It was in the nineties, less than a decade after Tufte’s theory, when the accumulation of information started to skyrocket with the advancement of the World Wide Web. Businesspeople seemed to be lacking even more time with more information to consider, and a minimalistic approach seemed like a solution.

    Minimalism did not only impact data visualization, but its effect also reached almost every corner of the human computer interaction (HCI) field. For example, as the internet became more widespread, search engines started to develop and became so powerful that they began to impose their own rules of the game. Because of the nature of how search engines work, the minimalistic structured design of web pages was more attainable for the engines to read and rank, and therefore more preferable and reachable for the audience.

    For similar benefits, like reach in webpages and efficiency in data visualizations, minimalistic design became so invasive in all computer interfaces over the years. Today, minimalistic design is usually described as “modern design” and recommended to every designer building a user-interaction system, from mobile apps to webpages to data visualizations.

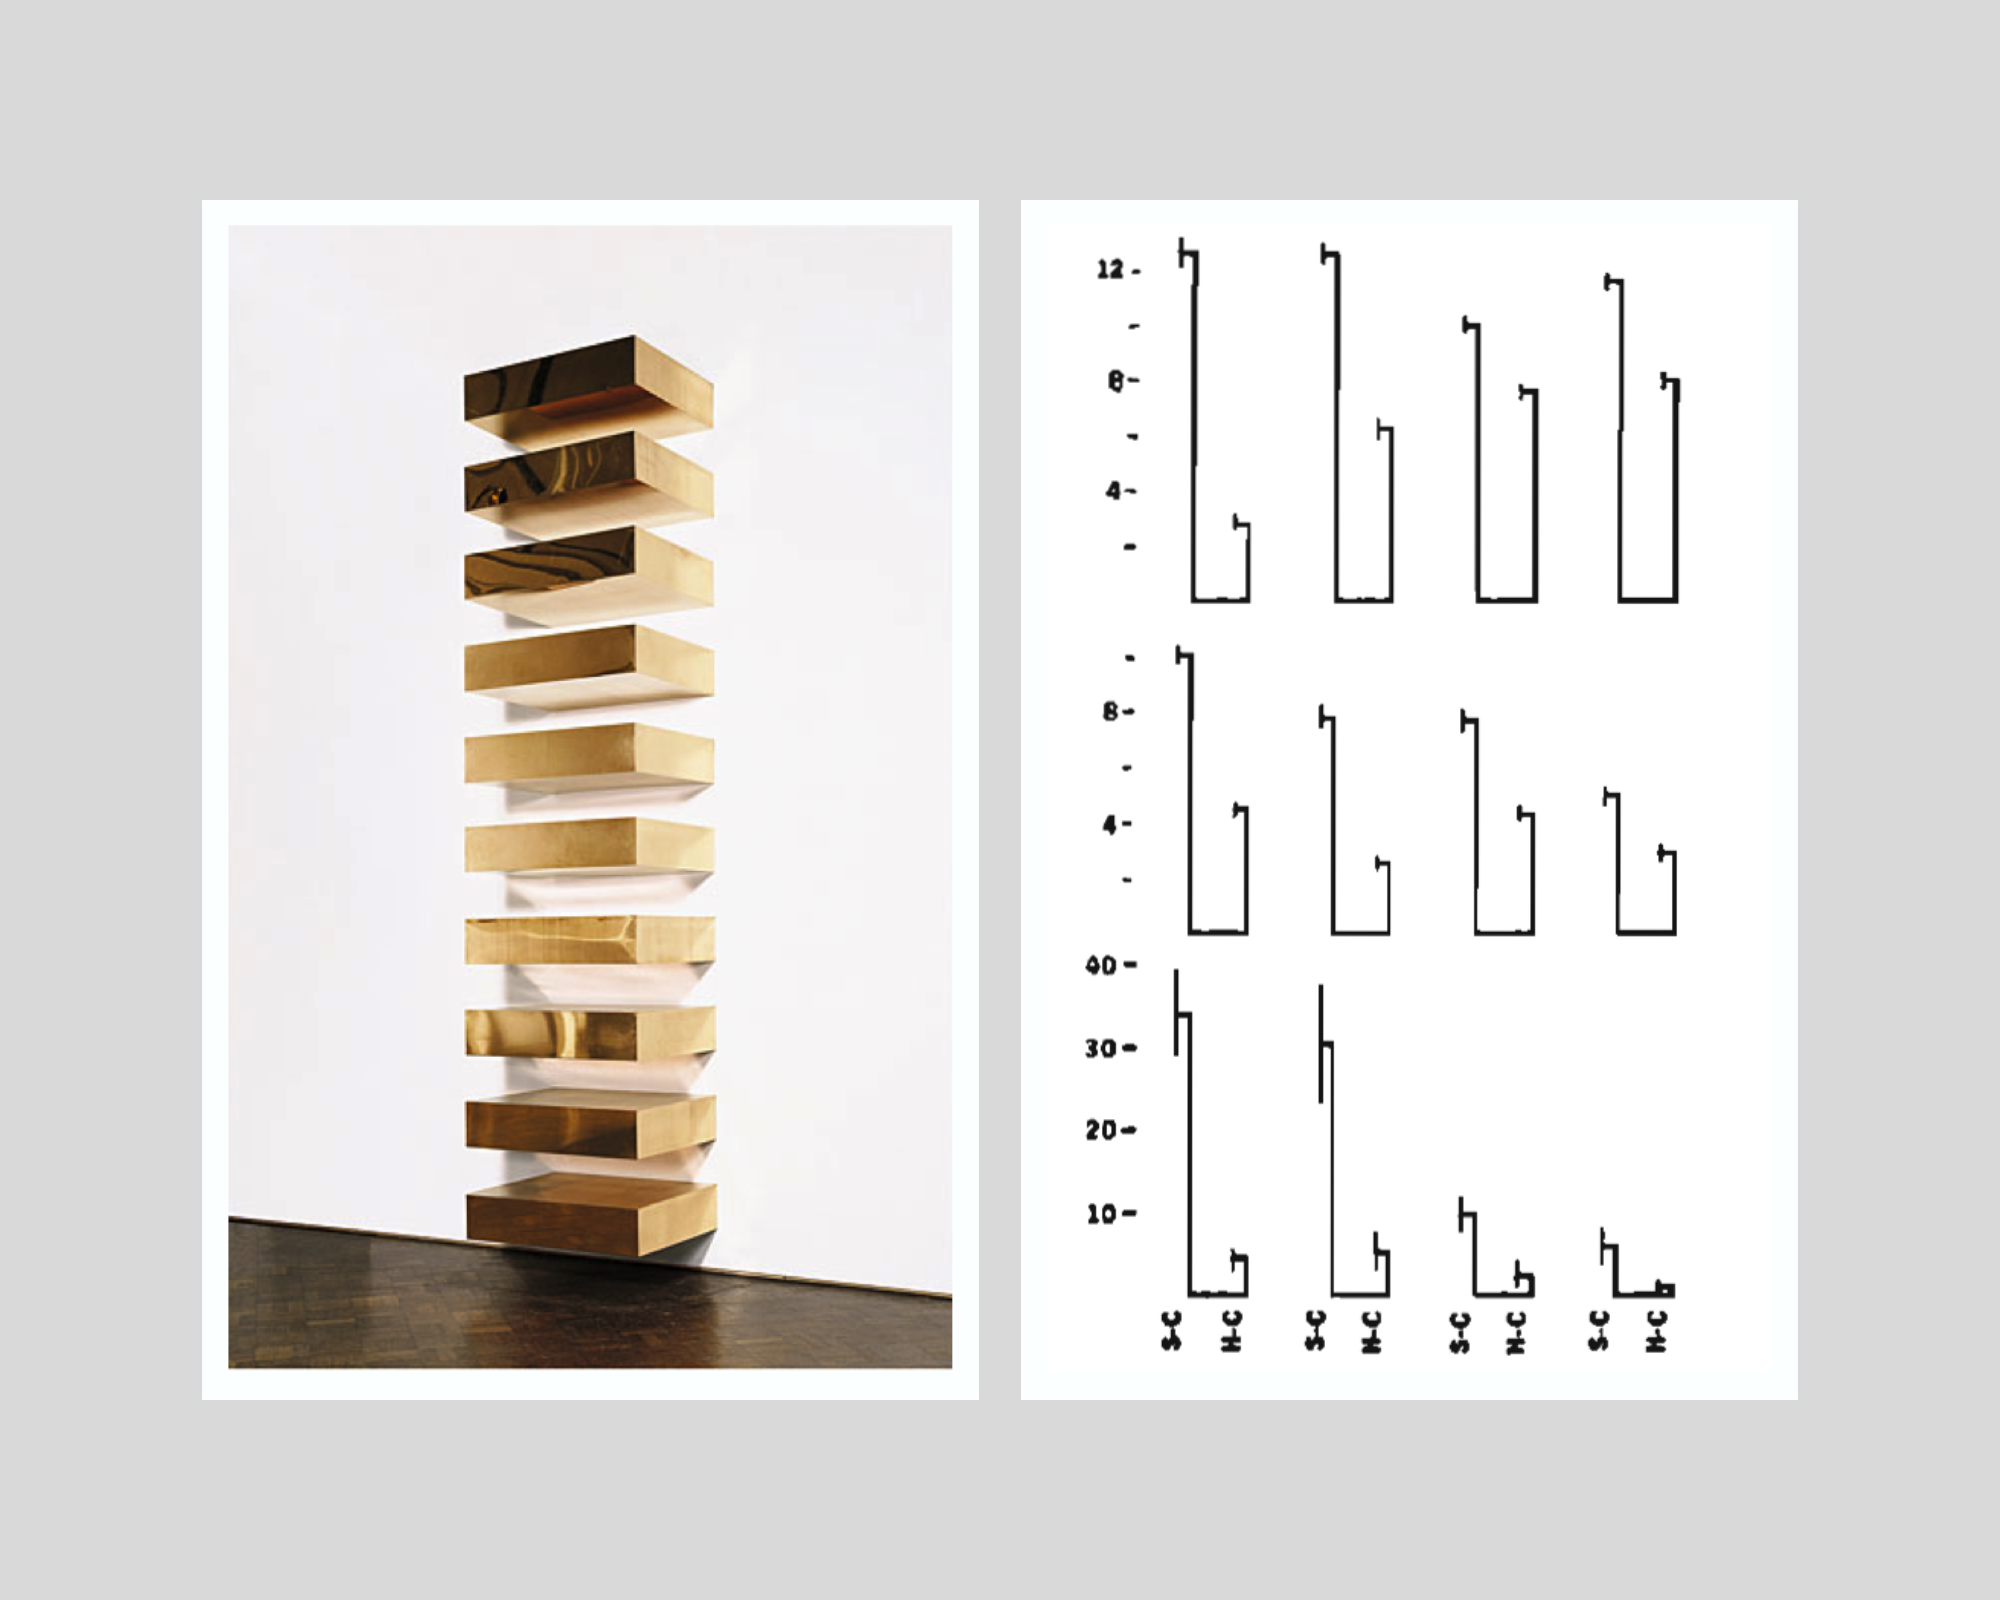
    Example for similarities between Tufte's pronciples and minimalism

    On the left: Donald Judd’s minimalist installation, Untitled, 1969 (photo from: Guggenheim Museum, New York) | On the right: Tufte’s minimalist variation of a double-bar chart with error lines. | Collage by Islam Salahuddin

    Reviews of data-ink ratio’s minimalism

    Despite  presenting his hypotheses as proven facts, Tufte had never empirically tested his promised achievements that can be reached by minimalistic design. It was not until the beginning of the nineties that academic research started to put the claims under the microscope.

    The initial research findings struggled to prove the hypotheses. However, a major multi-experiment research paper in 1994 found that some non-data-ink and redundant data-ink, especially backgrounds and tick marks on the y-axis, may decrease accuracy and increase response time (which is proportionally bad). Meanwhile, the other ink that Tufte considered to be chartjunk and called for its removal whenever possible, like axis lines, was proved to increase performance in some cases. The negative effect was clear in some chartjunk types, like axis lines, but was less certain in others, like three-dimensional charts.

    Such experiments were still built on the same proposition of Tufte that graphical excellency means clarity, precision, and efficiency but found that the relationship between data-ink ratio and excellency in that sense can hardly be linear as Tufte suggests. The paper states that “effects of ink are highly conditional on the features of the graph and task” and therefore “simple rules like Tufte’s will not suffice.” Instead of indicating that all non-data-ink and redundant data-ink should be erased, the authors call on data visualization designers to determine whether the use of any ink will facilitate or interfere with reading a graph, depending on its context.

    Later research even questioned Tufte’s components of graphical excellency, especially the presumed all-cases importance of response time factor. An empirical paper in 2007 found that users may prefer non-minimalistic visualizations over Tufte’s minimalistic ones, partially because they may find the latter boring. This is a criticism that both Minimalism art and statistics face and a perception that Tufte tried to avert with his rule. Boredom should not be treated as a minor problem because it means less ability to induce attention. A visualization’s ability to generate attention is the gateway to the viewer’s perception in the first place.

    Attention is one of the criteria that Tufte’s rule overlooks. Other significant factors are memorability and engagement. More advanced experiments in 2013 and 2015 re-asserted chartjunk as not always harmful. In some cases, it may even increase the memorability and engagement of a visualization. Attributes like color and human recognizable shapes, icons, and images can enhance memorability due to their ability to activate more parts of a viewer’s brain, leveraging its natural tendency towards what is familiar rather than what is just minimal.

    Despite their popularity, chartjunk and similar terms also appear to be highly open to interpretation among practitioners. Interpretation can be affected by an individual’s circumstances that include culture, personal style, preferences, and views, as well as constraints of skills, tools, and user’s priorities, according to a discourse analysis that was published in 2022.

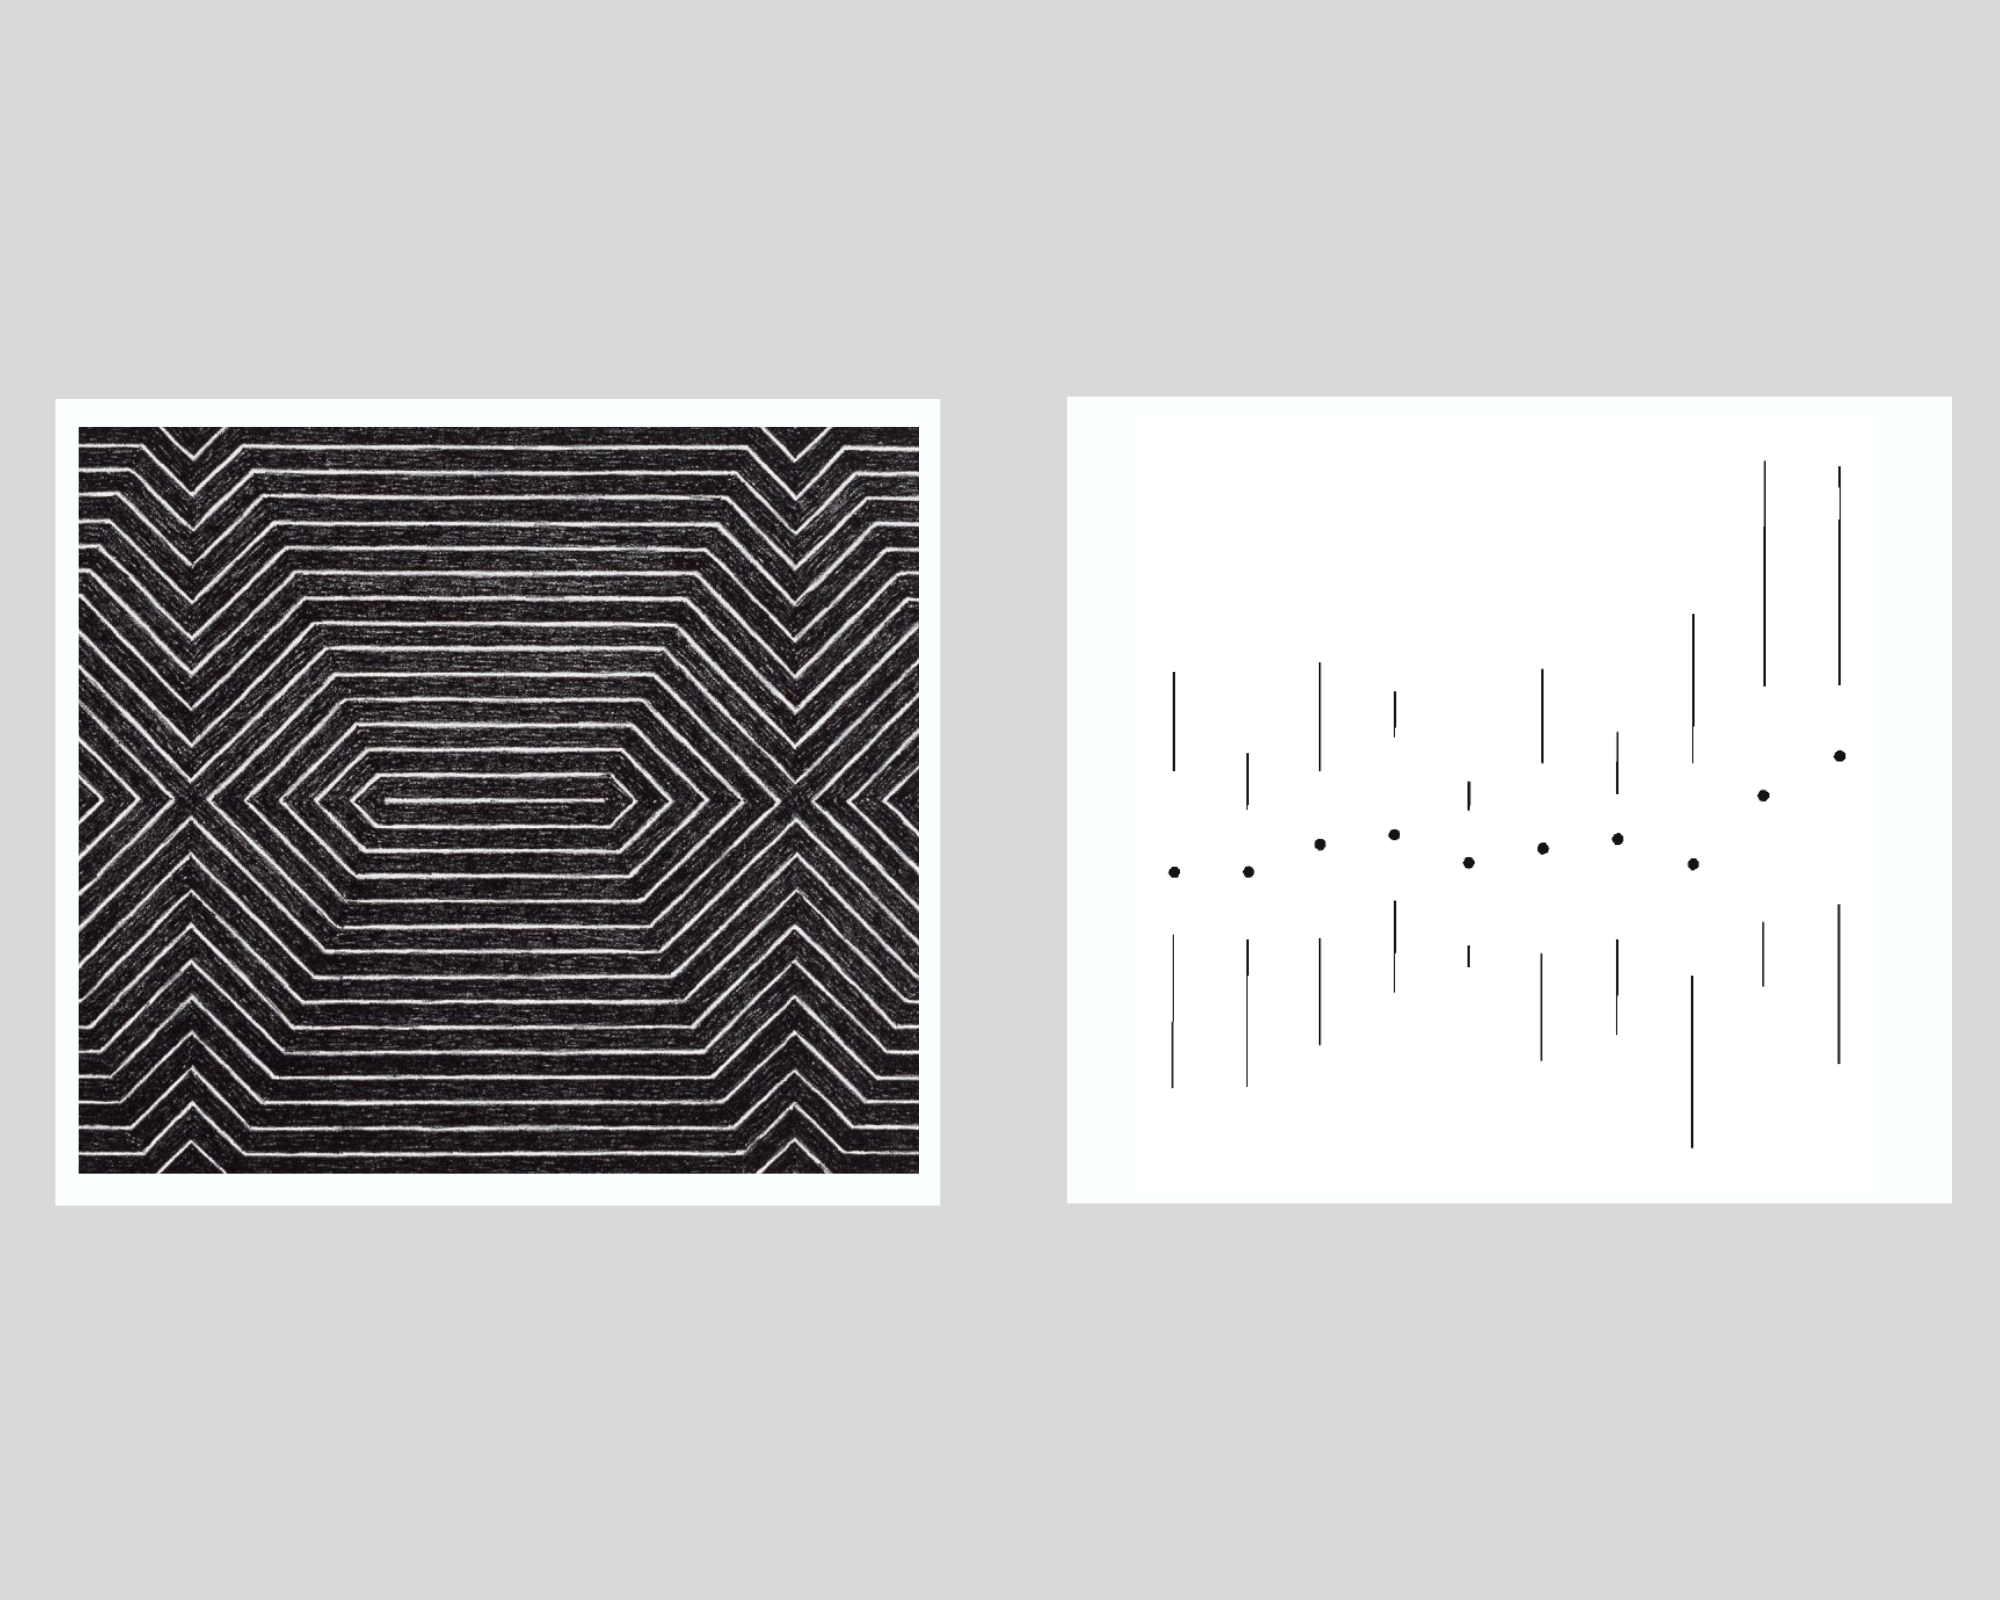
    Example for similarities between Tufte's principles and minimalism

    On the left: Frank Stella’s minimalist painting, title not known, 1967 (photo from Tate Modern) | On the right: Tufte’s minimalist variation of a multiple vertical box and whisker plot. | Collage made by Islam Salahuddin

    How to make sense of the previous discussions

    The growing body of research shows that data visualization is a task that can hardly be led by only a one-factor rule like data-ink ratio. It shows that even the simple task of choosing what elements to include or exclude in a visualization remains largely an uncharted territory and needs further examination.

    However, one of the common underpinnings that all theoretical works share is a consideration for the importance of context in which a visualization is designed. To be fair, even Tufte himself did not ignore this consideration after all and emphasized that certain principles have to be adopted “within reason.” Asserting the “reasonability” factor, he deliberately mentions in the Data-Ink Maximization chapter of his book that maximizing data-ink “is but a single dimension of a complex and multivariate design task.” He recognized the possible existence of factors other than excellency that come into play, including “beauty,” even if he did not prioritize them.

    Therefore, synthesizing all the critiques arising against Tufte’s rule of data-ink ratio appears to be possible by quoting Tufte himself. He said that determining to which extent the data-ink ratio should be maximized rests on statistical and aesthetic criteria.” This allows data visualization designers to figure out the sweet spot where a visualization delivers what it intends to and, at the same time, does not alienize itself for the sake of being minimal.

    All in all, minimalism can be considered one of the means to design a great data visualization, but not a goal. After all, the goal will remain to deliver the intended message to the audience so they can perceive it best.

    Want to understand how visual representations can support the decision-making process and allow quick transmission of information? Sign up for The KPI Institute’s Data Visualization Certification course.

    Data visualization post-Tufte: levers of chart-making and cognitive load

    FacebooktwitterlinkedinFacebooktwitterlinkedin

    Image source: Artem Podrez | Pexels

    Edward Tufte’s principles of data-Ink ratio have prevailed in data visualization since they were introduced in the 1980s. His theory has imposed a tendency towards a minimalistic style, defining excellence as clarity, precision, and efficiency and reducing the time users perceive information.

    Meanwhile, academic research that has put the American pioneering statistician’s teachings to test does not show the linear relationship between data-ink ratio and visualization’s excellency. Further research shed light on other important criteria that Tufte overlooked, like the ability of a visualization to induce attention, memorability, and engagement. Overall, the academic body of literature has strongly suggested that no simple rule like data-ink ratio can suffice in data designing.

    Debates among practitioners have been ongoing about the repeated notion of “less is more,” which leans back on Tufte’s teachings. Some believe that simplicity and quick perceiving should be the goals of all visualizations at all times. Others support embracing complexity and slow viewing time in some circumstances.

    As a response to these debates, two interesting frameworks have emerged to suggest more criteria that should be considered. The first is “Levers of Chart-Making” by Andy Cotgreave, a senior data evangelist at Tableau, and the second is “Cognitive Load as a Guide” by Eva Sibinga and Erin Waldron, data science and visualization specialists.

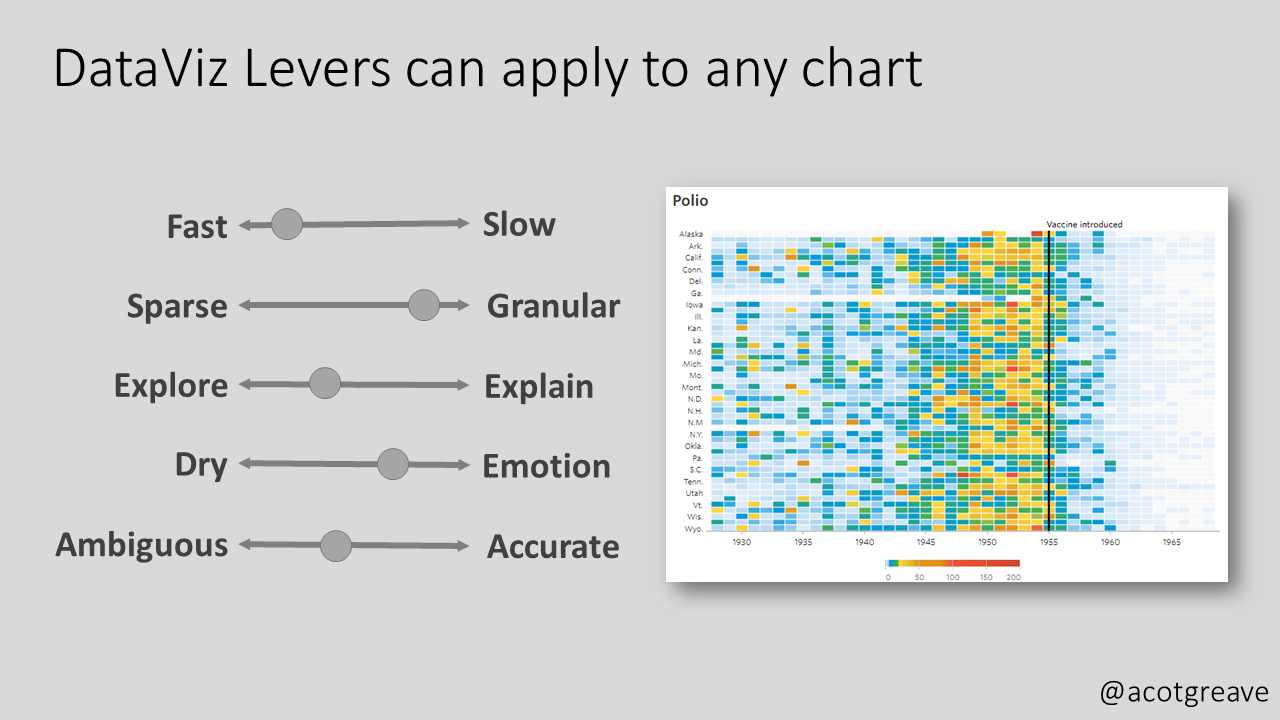
    Levers of chart-making


    Levers of chart making

    Image Source: The Sweet Spot

    Cotgreave suggested this under-formulation framework in the November 2022 edition of his newsletter The Sweet Spot. He put forward five scales of levers that “chart producers can use to enlighten, not bamboozle.” They are as follows:

    1. Speed to primary insight – How fast or slow insight is intended to be extracted from a graph According to him, “it is ok to make charts that take time to understand”.
    2. Granularity – How sparse or granular is the data that a chart intends to show?
    3. Explore or explain – whether a visualization is intended to give the users the opportunity to explore the data themselves (like self-service dashboards) or to be accompanied by an explaining presentation
    4. Dry or emotional – refers to how serious the way of presenting the data is versus how informal  and relevant it is to non-data people. According to Cotgreave, an example of the serious approach is a normal column chart and for the emotional, a necklace of which the bead’s size represents the same underlying data.
    5. Ambiguity vs. accuracy – For Cotgreave, there can be intended ambiguity in chart-making instead of clear accuracy.

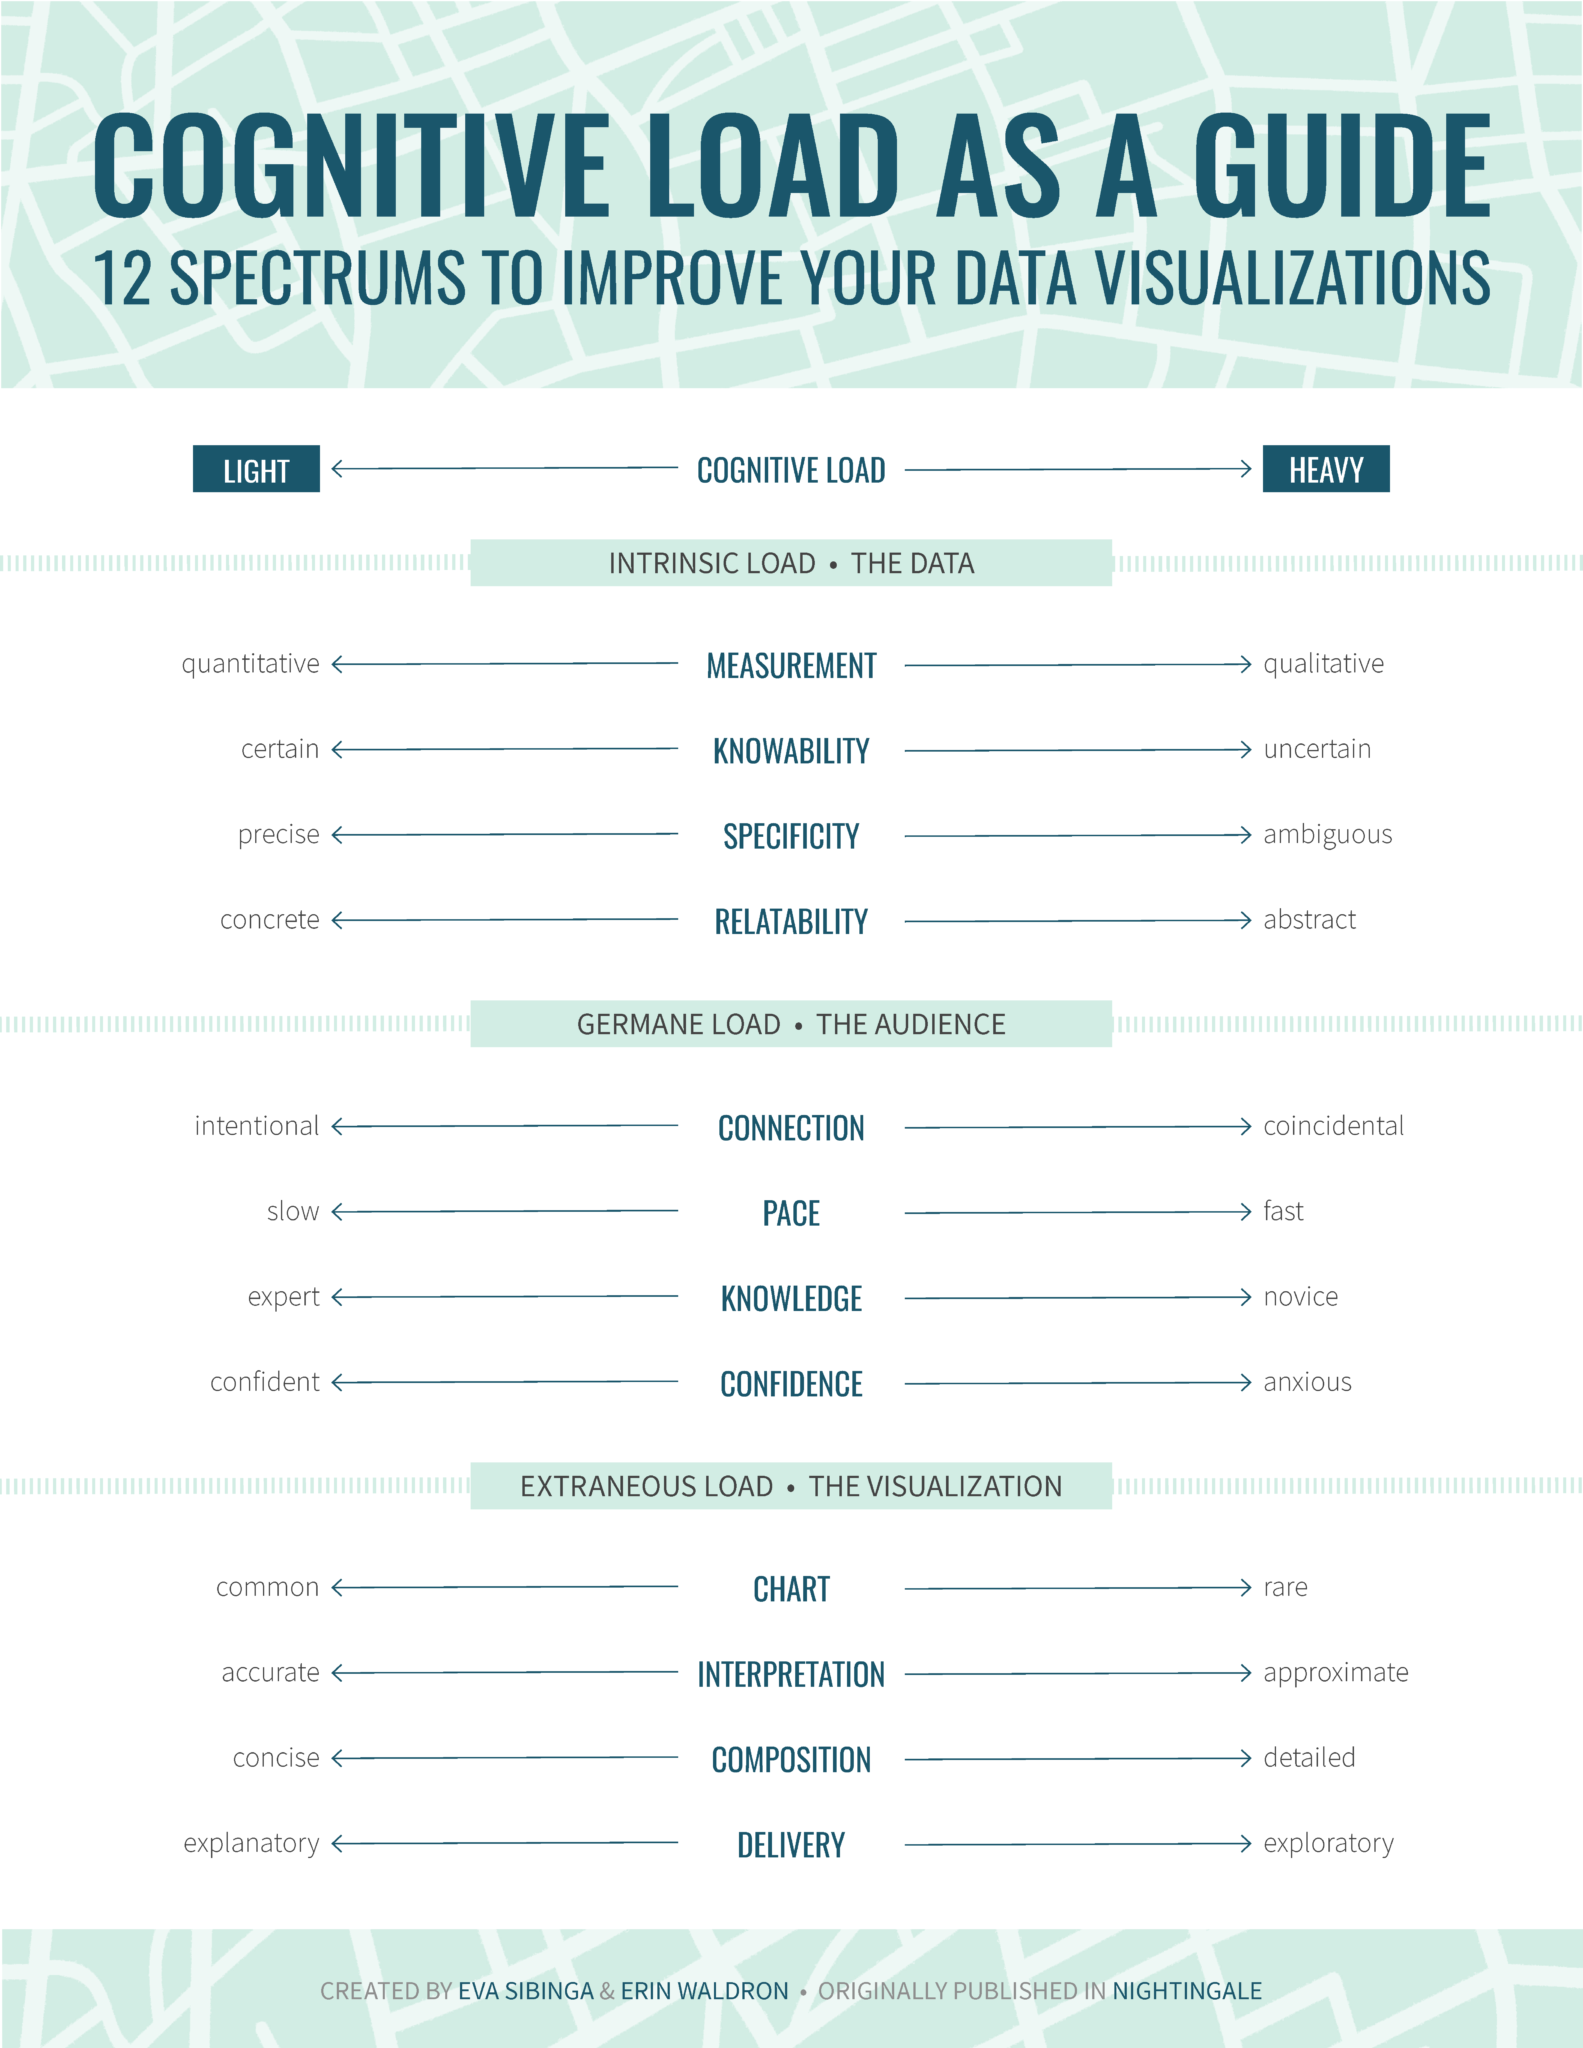
    Cognitive load as a guide

    Cognitive load as a guide

    Image Source: Nightingale

    Cognitive load is a more detailed and rigid framework that takes its inspiration from the psychology of instructional design. Suggested by Sibinga and Waldron, the framework was published by the Journal of the Data Visualization Society (Nightingale) in September 2021.

    Cognitive load proposes 12 spectra, offering “an alternative to one-size-fits-all rules” and aiming to “encourage a more nuanced strategy” for data visualization. Divided into three categories, the spectra are supposed to “gauge the complexity of our data on one side, identify the needs of our audience on the other, and then calibrate our visualization to successfully bridge the gap between the two.”

    Intrinsic load – This is the first group of spectra that is concerned with the data itself. It considers the inherent level of complexity in the data that a designer is tasked to explain with a visualization. The included spectra are:

    • Measurement (quantitative vs. qualitative) – According to the authors, quantitative data has less cognitive load (easier to perceive) than qualitative data. That is because the former usually has obvious measuring units, like dollars or miles, while the latter usually needs a conceptual rating scale, like satisfaction rate from 1 to 5.
    • Knowability (certain vs. uncertain) – Data collected from the whole population is easier to perceive than data estimated depending on a sample or predicted for the future. This is because the former usually has a high level of certainty that is easier to perceive than the uncertainty that comes with the latter, intertwined with its inevitable statistical margins of error.
    • Specificity (precise vs. ambiguous) – Undebated data categories, like blood type or zip codes, tend to be easier to perceive than socially determined concepts, like gender, race, and social class.
    • Relatability (concrete vs. abstract) – How relatable is the data to what humans see in everyday life? Concrete data would be small numbers like the cost of lunch and one’s age, while abstract data would be conceptual ones like GDP and the age of the earth.

    Germane load – The second group of spectra is concerned with the audience and how ready they are to process the new information shown by a visualization. The included spectra are:

    • Connection (intentional vs. coincidental) – How will the audience have the first look at the visualization? Intentional viewers are likely better propped to perceive the visualization than viewers who stumble upon it by accident.
    • Pace (slow vs. fast) – Slow viewers are the ones that have more time in hand and therefore +have more ability to perceive a visualization (interpreting into lighter cognitive load).
    • Knowledge (expert vs. novice) – Expert viewers are the ones who are already familiar with the subject and therefore will have to afford lighter cognitive load when viewing a visualization.
    • Confidence (confident vs. anxious) – This spectrum addresses the intersection of the audience and the data reporting format. The cognitive load that is required from an audience familiar with the data reporting format, such as an interactive dashboard and a data-based report, will require lighter cognitive load than the one that is encountering such a channel for the first time.

    Extraneous load – The final group addresses how new information is presented. The authors believe that these are the criteria where a designer has the most control and should therefore be considered last. The advice to determine a visualization’s place on the following spectra is by answering the question: “Given the existing intrinsic and germane loads, how much more cognitive load are we comfortable adding to the mix?”

    • Chart type (common vs. rare) – Chart types like bar charts need lighter cognitive load than uncommon ones, like violin charts or rose diagrams and the more innovative ones.
    • Interpretation (accurate vs. approximate) – Does the chart aim to deliver precise values or paint a wide picture? According to the authors, charts delivering specific values tend to take a lighter cognitive load than the ones dealing with overall objectives.
    • Composition (concise vs. detailed) – This spectrum assumes a high data-ink ratio and no chartjunk (from Tufte’s concepts) are already in place and then asks, how dense is the information on the page? Less dense visualizations require lighter cognitive load.
    • Delivery (explanatory vs. exploratory) – Does the data report explain itself, or is built to be explored? Exploration, naturally, takes more cognitive load than a self-explaining visualization.

    How to make sense of all the previous discussions

    Levers of chart-making and cognitive load as a guide are two of the recently suggested frameworks that offer a more complex approach to the task of data visualization. The two have similarities, like their consideration of complexity, granularity, and way of delivery. They differ from Tufte’s approach mainly through their acceptance of the need to slowly perceive designs in some circumstances. Cognitive load still deliberately pre-assumes applying data-ink ratio principles beforehand.

    Therefore, no framework is likely to totally replace the others. At best, they tend to complement each other to cover the vast territory of the data visualization domain.

    Data-ink ratio principles remain a good point to start as it best fits most business contexts. It can also help designers keep in mind the point of their design and avoid getting distracted amidst all the available software tools today. However, considering the emerging frameworks can make the practice more nuanced for tackling different needs, messages, and audiences.

    The final determinant of how to incorporate the three frameworks -and any other emerging ones- in practice will remain to be the context of the visualization. A better understanding of the audience, the message, and the medium is key before using the different frameworks to decide on how information should be delivered.

    Want to understand how visual representations can support the decision-making process and allow quick transmission of information? Sign up for The KPI Institute’s Data Visualization Certification course.

    Data Visualization as a Form of Sculpting

    FacebooktwitterlinkedinFacebooktwitterlinkedin

    Image Source: Lukas | Pexels

    “If communication is more art than science, then it’s more sculpture than painting. While you’re adding to build your picture in painting, you’re chipping away at sculpting. And when you’re deciding on the insights to use, you’re chipping away everything you have to reveal the core key insights that will best achieve your purpose,” according to Craig Smith, McKinsey & Company’s client communication expert.

    The same principle applies in the context of data visualization. Chipping away is important to not overdress data with complicated graphs, special effects, and excess colors. Data presentations with too many elements can confuse and overwhelm the audience. 

    Keep in mind that data must convey information. Allow data visualization elements to communicate and not to serve as a decoration. The simpler it is, the more accessible and understandable it is. “Less is more” as long as the visuals still convey the intended message.

    Finding the parallel processes of exploratory and explanatory data visualization and the practice of sculpting could help improve how data visualization is done. How can chipping away truly add more clarity to data visualization?

    Exploratory Visualization: Adding Lumps of Clay

    Exploratory visualization is the phase where you are trying to understand the data yourself before deciding what interesting insights it might hold in its depths. You can hunt and polish these insights in the later stage before presenting them to your audience.

    In this stage, you might end up creating maybe a hundred charts. You may create some of them to get a better sense of the statistical description of the data: means, medians, maximum and minimum values, and many more. 

    You can also recognize in exploratory if there are any interesting outliers and experience a few things to test relationships between different values. Out of the 100 hypotheses that you visually analyze to figure your way through the data in your hands, you may end up settling on two of them to work on and present to your audience.

    In the parallel world of sculpting, artists do a similar thing. They start with an armature-like raw data in designing. Then, they continue to add up lumps of clay on it in exploratory visualizations. 

    Artists know for sure that a lot of this clay will end up out of the final sculpture. But they are aware that this accumulation of material is essential because it starts giving them a sense of ideal materialization. Also, adding enough material will ensure that they have plenty to work with when they begin shaping up their work.

    In the exploratory stage, approaching data visualization as a form of sculpting may remind us to resist two common and fatal urges:

    • The urge to rush into the explanatory stage – Heading to the chipping away stage too early will lead to flawed results.
    • The urge to show all of what has been done in the exploratory stage to the audience, begrudging all the effort that we have put into it – When you feel that urge, remember that you don’t want to show your audience that big lump of clay; you want to show a beautified result.

    Explanatory Visualization: Chipping Away the Unnecessary

    Explanatory visualization is where you settle on the worth-reporting insights. You start polishing the visualizations to do what they are supposed to do, which is explaining or conveying the meaning at a glance. 

    The main goal of this stage is to ensure that there are no distractions in your visualization. Also, this stage makes sure that there are no unnecessary lumps of clay that hide the intended meaning or the envisioned shape.

    In the explanatory stage, sculptors use various tools. But what they aim for is the same. They first begin furtherly shaping the basic form by taking away large amounts of material. It is to ensure they are on track. Then, they move to finer forming using more precise tools to carve in the shape features and others to add texture. The main question driving this stage for sculptors is, what uncovers the envisioned shape underneath?

    In data visualization, you can try taking out each element in your visualization like titles, legends, labels, colors, and so on. Then, ask yourself the same question each time, does the visualization still convey its meaning? 

    If yes, keep that element out. If not, try to figure out what is missing and think of less distracting alternatives, if any. For example, do you have multiple categories that you need to name? Try using labels attached to data points instead of separate legends.

    There are a lot of things that you can always take away to make your visualization less distracting and more oriented towards your goal. But to make the chipping away stage simpler, C there are five main things to consider according to Cole Nussbaumer Knaflic as cited in her well-known book, Storytelling with Data: 

    • De-emphasize the chart title; to not drive more attention than it deserves
    • Remove chart border and gridlines
    • Send the x- and y-axis lines and labels to the background (Plus tip from me: Also consider completely taking them out)
    • Remove the variance in colors between the various data points
    • Label the data points directly

    In the explanatory stage, approaching data visualization as a form of sculpting may remind us of how vital it is to keep chipping away the unnecessary parts to uncover what’s beneath, that what you intend to convey is not perfectly visible until you shape it up.

    Overall, approaching data visualization as a form of sculpting may remind us of the true sole purpose of the practice and crystalize design in the best possible form.

    Sign up for The KPI Institute’s Certified Data Visualization Professional course to learn the fundamentals of creating visual representations, the most effective layouts, channel selection, and reporting best practices.

    THE KPI INSTITUTE

    The KPI Institute’s 2026 Agenda is now available! |  The latest updates from The KPI Institute |  Thriving testimonials from our clients |